A bank team has too few examples of customers who signed up for a term deposit, so it asks GPT to create more. It gets a bigger file and no way yet to tell whether the model will do better.
AI training data is the set of records a model learns from for one task. Data that GPT or Claude created or revised becomes usable training data only after someone checks that it reflects real cases, keeps the information the task needs and holds up in a before-and-after comparison on the same evaluation records.
Adapted from GPT Created or Fixed Your Data. Is It Ready for AI? by Minchan Chung, Co-Founder and Co-CEO of CUBIG, on the CUBIG Tech Blog (November 2026).
In CUBIG’s bank marketing experiment (October 2026), with the same random forest settings, prepared training data found 56 customers who had signed up instead of 31 on the same 824 original evaluation records, while customers wrongly flagged as having signed up rose from 16 to 39. Both numbers matter for deciding whether the prepared data works for the task.
Key takeaways
- A generated or revised file is a candidate, not finished training data. Added examples have to reflect real cases, and removed or created fields must not drop information the task needs.
- Which fields belong in the training data depends on when the decision is made. Call duration can describe a finished call; it cannot inform a decision about whom to call tomorrow.
- A changed file does not show by itself that the change helps. The evidence is a comparison after training, on the same original evaluation records.
What makes AI training data ready for a task?
Teams turn to GPT or Claude in two common ways. The first is “create more examples of these customers for training”, when one outcome is rare. The second is “look at what is wrong with our data and improve it”, when the records exist but the model still struggles. Either way, the team receives extra examples or a revised file, and someone still has to decide whether that data is suitable for training.
Three checks decide it. Added examples need to reflect the relevant characteristics of real customers. Fields that were removed or created must not drop information the task depends on. And the model’s results after training have to be compared with the results before: whether it identifies more of the customers who signed up, and whether it makes more mistakes elsewhere.
| Question | A new or revised file | Training data ready for the task |
|---|---|---|
| Examples | More records of the rare outcome | Records that reflect the relevant characteristics of real cases |
| Fields | Fields removed, created or kept as they were | Fields the task can use at the moment of the decision, with no useful information lost |
| Evidence | The file itself | A before-and-after result on the same original evaluation records |
Why does the decision time change which fields belong in the training data?
What needs to change depends on the job. When a team analyses completed sales calls, call duration is a fair input. When the team decides whom to call tomorrow, it does not yet know how long those calls will last. Keeping the field because it exists in the historical records would let the model answer using information unavailable at the moment of the decision.
Even with the same customer records, the team needs to settle which decision the model supports, and when that decision is made, before choosing the examples and input fields. A generated or revised file cannot settle that question; the people who own the decision have to.
What changed in the bank marketing experiment?
The bank marketing experiment explored how this kind of preparation changes results. The team selected 15 of the 20 input fields for a random forest model and added 897 training examples of customers who had signed up, the less common group. The number of examples of customers who had not signed up stayed the same, so the preparation targeted the shortage.
The random forest settings stayed the same, and a model was trained separately on the original and the prepared data. Both versions were tested on the same 824 original records, not on newly generated examples.
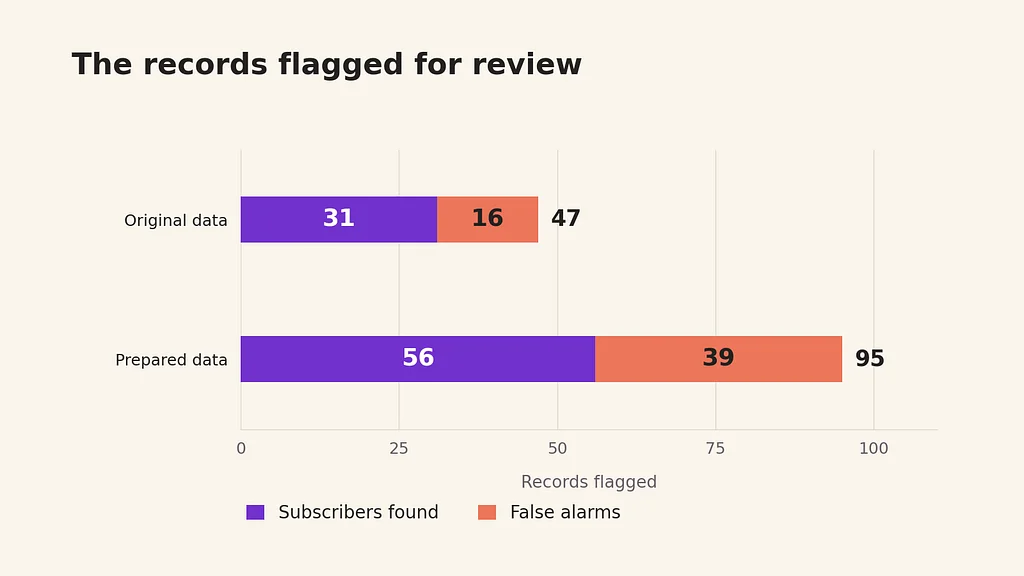
Finding more customers who signed up looks encouraging, but the extra mistakes count too, which is why data preparation has to end in a comparison of results. The experiment has two limits. Field selection and added examples were applied together, so the contribution of each step cannot be isolated. And the inputs included call duration, so the results are post-call classification, not evidence of choosing better people to call tomorrow.
What work sits behind a request to fix our data?
A request to “make more data” or “fix our data” holds several decisions: which customers the company wants to distinguish, when it will make the decision, and which relationships between records must be preserved when the data changes. Those conditions give the team a basis for judging whether the revised data fits the job.
A team can build this process itself with GPT or Claude. Doing so means connecting the request to generate or revise data with the choice of input fields and a comparison under the same conditions. The work continues after a new file arrives: the file has to become usable training data, and its effect has to be checked, as in any AI model evaluation.
How does CUBIG connect data preparation with a before-and-after check?
CUBIG built Syntitan, its AI-ready data platform, to select relevant fields, supplement missing examples and compare results before and after preparation as one connected process. In the bank marketing experiment, the software produced the revised training data, the comparison results and the code needed to rerun the model training and scoring in that comparison, though not the upstream preparation steps, so the team could inspect the prepared data and its results without implementing the method from scratch.
CUBIG is now refining how a company’s own requirements enter that work. Someone predicting before a call needs different inputs from someone analysing records after it, and the goal is for a customer to explain the job and have the software fill the gaps, adapt the existing data and check whether the result improved.
A prepared file still needs a person to judge whether its trade-offs fit the task. Try it on your data.