What Does It Mean to Fix Data for AI?
Most companies start preparing for AI by cleaning up their data. They remove duplicates, fill in missing values, and connect systems that never talked…
Most companies start preparing for AI by cleaning up their data. They remove duplicates, fill in missing values, and connect systems that never talked…
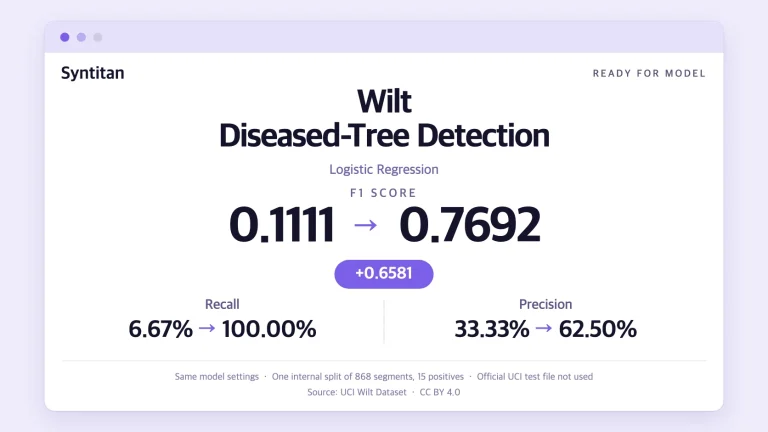
Explore the UCI Wilt Dataset with Syntitan: logistic regression F1 rose from 0.11 to 0.77. See four-model results, false alarms, and evaluation limits.
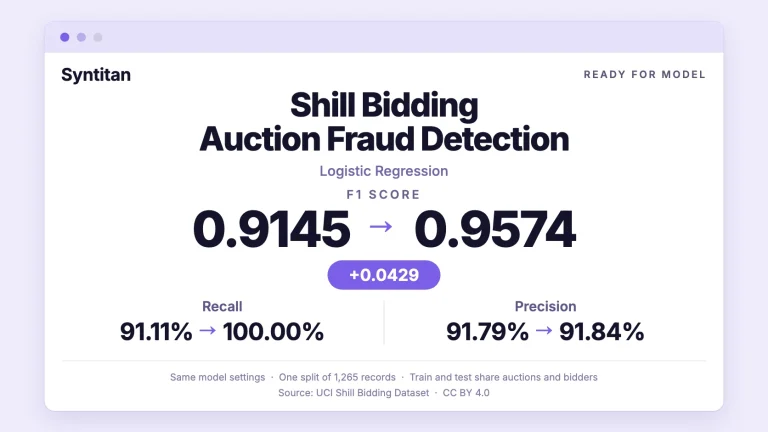
On the UCI Shill Bidding Dataset, Syntitan raised logistic regression F1 from 0.91 to 0.96. See four models, the trade-offs, and what the kit…
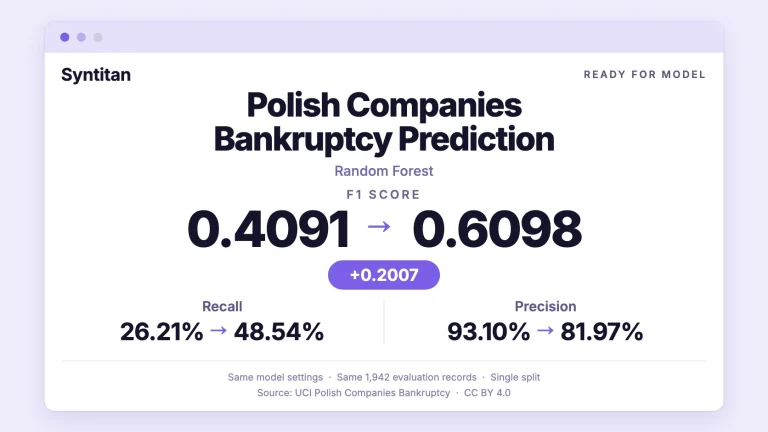
On the UCI Polish bankruptcy dataset, Syntitan data preparation raised Random Forest F1 from 0.41 to 0.61. Compare four models and their trade-offs.
Platforms are adding data health signals and context layers for AI agents. Teams still need to test whether the answers meet the criteria for…
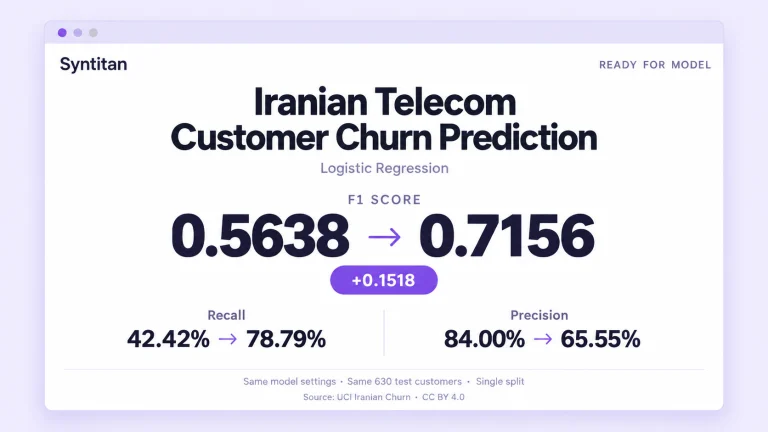
On the UCI Iranian Churn dataset, Syntitan data preparation raised telecom churn prediction F1 from 0.56 to 0.72 for Logistic Regression, with more false…
Gartner predicts 60% of AI projects without AI-ready data will be abandoned. Here are 12 agentic AI companies to watch in 2026, by role,…
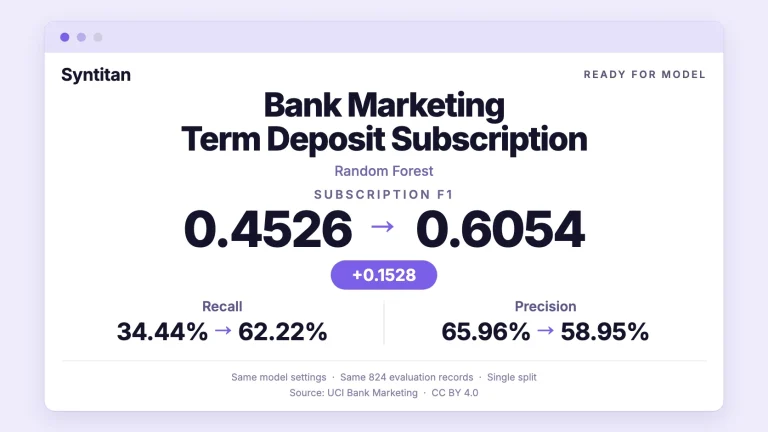
On the UCI Bank Marketing dataset, data preparation raised a Random Forest's subscription F1 and recall but added false positives. What the result shows.
LLM data privacy often starts by substituting values before a model call. Here are the details an AI task may need to keep, and…
The FSB finalized 12 AI sound practices. We examine what its data governance and performance guidance means for data versions, evaluation records and rechecks.
Two recent AI agent benchmarks show why consistent data and available evidence do not guarantee success on a specific business task.
Synthetic data use cases now include work scenarios across documents, email, and chat. How to check that a scenario set covers the situations that…
No results.