Hello, this is CUBIG the company behind Syntitan, the AI-ready data platform for enterprise AI.
A widely cited MIT report says 95% of generative AI pilots returned no measurable profit last year, and the reason everyone repeats is the one MIT’s own data refuses to support.
Enterprise AI adoption is the work of turning a capable model into a result a business can book on its P&L, and most of it is stalling at exactly that step. In its State of AI in Business 2025 report, MIT’s NANDA initiative found that only about 5% of generative AI pilots reach real operational or financial impact. The other 95% spend the budget and move nothing on the books, a split the researchers named the GenAI Divide. The number is now widely quoted in boardrooms and pitch decks. This piece reads it through one lens: what the 95% is actually being blamed on, what MIT’s data says instead, and why the gap between those two answers points at a problem nobody is selling a course for.
What the 95% number does to enterprise AI adoption
A failure number that large does not stay a research finding for long. It becomes a sales motion. Within weeks of the report, the dominant reading had settled into a single story: the pilots failed because the buyers were not ready. Not strategic enough, not mature enough, not transformed enough. The fix on offer is more transformation work and more strategy engagements. The 95% became a reason to hire the people who explain the 95%.
There is a second reading, popular among investors and operators, that the failure is organizational. Data sits trapped in departments, teams fight over ownership, and the AI never reaches the workflow it was bought for. That reading is closer to the ground, and it is partly right. But it tends to arrive with invented precision, a clean pie chart claiming some exact share is “politics” and some other share is “code.” The MIT report does not publish that split. Attaching it to MIT borrows authority the data does not give.
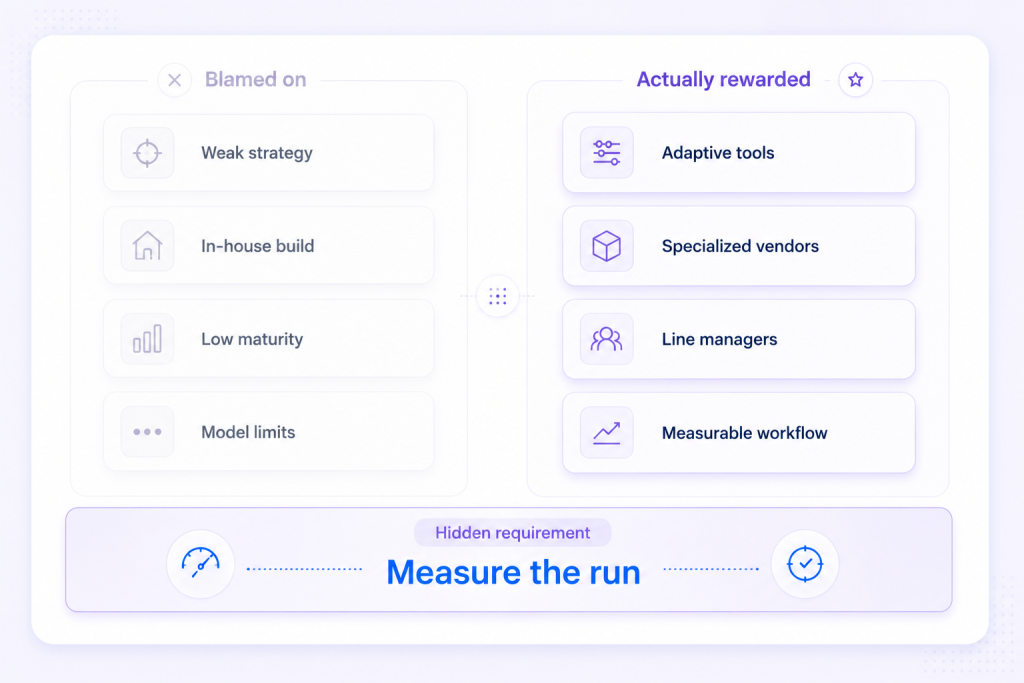
Read the report’s own findings and a different picture shows up. MIT points at a learning gap: tools that do not retain feedback or adapt to context cannot scale past the demo, no matter how strong the underlying model. The research also found that buying from specialized vendors and building partnerships succeeded more often than internal builds. And the pilots that worked tended to be driven bottom-up by line managers, not handed down from a central AI lab. None of that is a strategy deficit. It is a question of whether the system adapts and whether anyone can see it working.
Every row on the right shares a hidden requirement. To reward an adaptive tool, you have to see it adapt. To prefer the vendor that worked, you have to know it worked. To credit the line manager’s deployment, you have to attribute the result to it. The whole of MIT’s success column rests on a capability the failure column never mentions: the ability to measure what a given AI run actually produced. That is where the more useful version of this conversation starts.
No measurable ROI is first a measurement problem
Strip the slogans and the 95% finding says something narrow and precise. These pilots produced no measurable return. Measurable is the load-bearing word. A pilot can move a real number and still land in the 95% if no one can prove the AI is what moved it. A proof you cannot reproduce is a proof that does not survive the move from the demo to the floor.
Here is how that happens. The same model runs in the first quarter against one set of records and lifts a metric. It runs again in the second quarter against records that have quietly changed, and the lift is gone. Was that the model, the prompt, the team, or the fact that the input data was in a different condition the second time? With no way to reconstruct the state each run executed on, the question has no answer. And an answer is exactly what the next budget cycle demands. A result you cannot attribute is a result you cannot defend, and a result you cannot defend reads as a failure in the meeting that decides funding.
So a meaningful share of the 95% is AI that did something once and could not prove it twice. The precondition for measuring return on AI is the ability to reproduce the conditions a result was produced under. That sits underneath strategy, not after it. A flawless transformation program can still fail this test, because the test is about the data the model ran on, not the deck the consultants left behind.
Why so much AI readiness is staged
The same blind spot runs through how readiness gets sold. Many AI readiness assessments are a claim made once. A team assembles the scorecard, presents it, the room nods, the project gets funded. Nothing in that ritual requires the state being described to still hold next month, or to have been reproducible when it was described. A one-time claim can be arranged for the day of the review. A claim arranged for one day is theater.
A better questionnaire does not fix this, because the problem is structural rather than a matter of rigor. Readiness has to be checked against a specific AI task and the data a result actually used, instead of asserted as a figure in a slide. When a result has to be checked against the data it ran on, there is no scorecard to hide behind. This is the part of the current wave worth watching. A great many people are being trained to produce the assessment. Far fewer are being asked whether the thing assessed survives a second look.
The wall every pilot hits in production
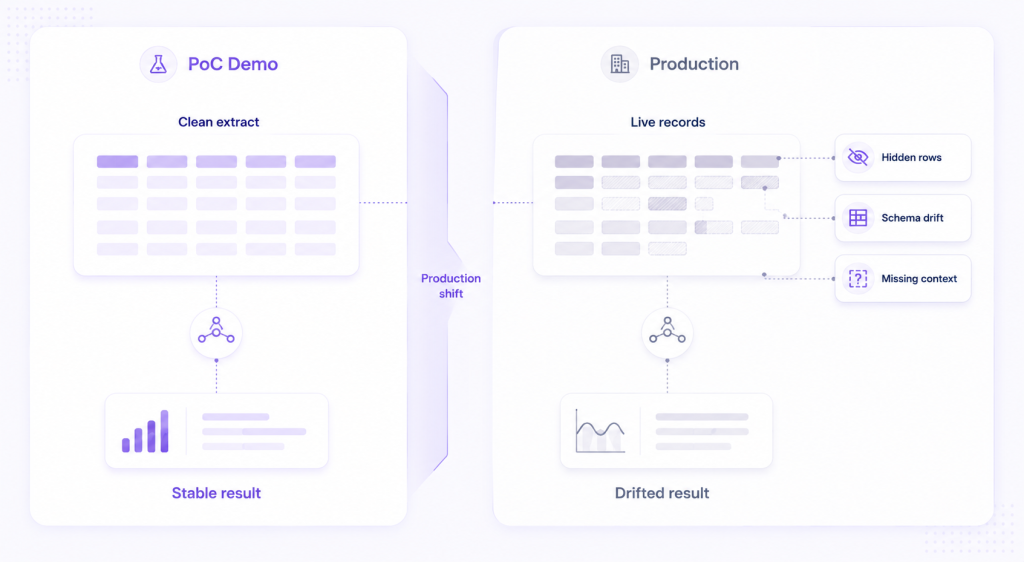
Sit with one project and the abstraction turns concrete. The proof-of-concept runs on a clean extract, the demo lands, the pilot is approved. Then the work moves into production and the ground shifts. The model now reads live records instead of the curated sample. Permissions hide rows the pilot could see. A column that was fully populated in March comes back half-null in June after an upstream system changed. Context that lived in one analyst’s head was never written down. Weeks later a result looks wrong, and no one can rebuild the exact data the model ran on to explain why.
Much of today’s engineering effort goes into controlling this with specs, gates, and evaluation loops. That is good discipline, and it catches one kind of drift, the kind that lives in code and process. It does not touch the other kind. Same pipeline, same prompts, next month’s data, and the output moves while nothing in the code changed. A model rarely breaks the way a test suite is built to catch. It passes the demo, reaches production, and drifts three weeks later when the data state under it is no longer the state it was validated against. Gartner has put a figure on the cost: in February 2025 it predicted that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data. In the same release, a survey of 1,203 data management leaders found 63% of organizations either lacked the right data management practices for AI or were unsure they had them. Data state is one driver of the GenAI Divide among several, including strategy and integration. It earns attention because it is the one that does not announce itself in the demo. We trace the mechanics in why AI fails after deployment.
Where this leaves CUBIG, and the teams running the pilots
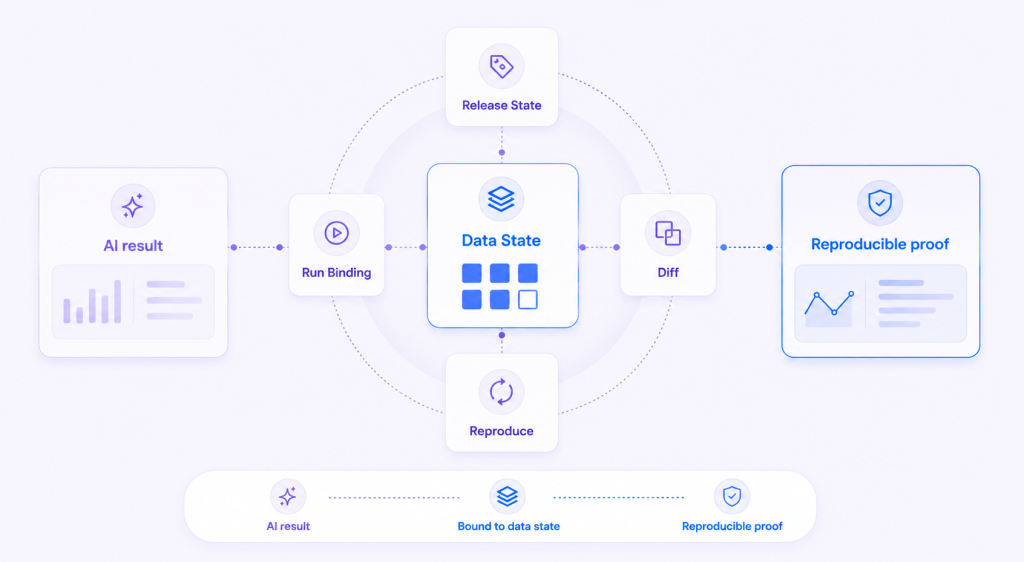
CUBIG does not sell strategy, and it does not replace the teams doing the deployment work. It takes on a piece of that work that is otherwise redone by hand on every engagement: preparing data for a specific AI task, checking it under agreed conditions, and keeping each processed result as a Version. A few terms make the layer concrete:
- Data state. The condition of the data a model ran on, its contents, schema, permissions, and context at the moment a result was produced.
- Version. A referenceable version of a data state. In Syntitan, each successful processing step creates a new Version, so a result is tied to the data it came from rather than to a memory of it.
- Comparison with the previous state. Checking a result against the data used at the time and comparing it with an earlier Version, so a result is defended with evidence rather than a screenshot. Tracking and reuse after changes are planned for December.
This is what AI-ready data means in practice. It is not tidy data. It is data prepared and checked for a specific AI task, with a record of which Version a result used. The 5% that cleared the GenAI Divide did not necessarily have better strategy than the 95%. What lets a team defend the spend and earn the next round is a result it can attribute and repeat. As enterprise AI adoption scales, the teams that move from the 95% to the 5% will be the ones that stop reassembling data state by hand and start carrying it as infrastructure. CUBIG’s platform, Syntitan, prepares and checks enterprise data for a specific AI task and keeps each processed result as a Version. Its data preparation engine, DTS, turns locked, scarce or regulated data into AI-ready data for training, testing, evaluation and sharing.
Before your next AI pilot
Five questions for anyone running or funding an AI pilot. The more of these that land on “no,” the more your real constraint is data state, the one no strategy engagement resolves on its own.
- Can you name the exact data state a given AI result was produced on?
- Would the same inputs, run again today, return the same output?
- When permissions or schema change, do your pilots survive the move to production?
- Could you defend a specific result to a CFO with evidence rather than a screenshot?
- Is data-readiness and proof rebuilt by hand each pilot, or carried as a reusable layer?
Try it on your data, free.
Run a sample proof on your own data for a specific AI task.