To reproduce an AI incident, you recreate the exact data state and execution conditions that produced the wrong output, then rerun the model against that bound state until the same result appears on demand.
Most teams cannot do this. When a production model returns a bad answer, the code is still in git and the model weights are still in the registry, but the data the model actually read has already moved on. The AI Incident Database catalogs a growing number of real-world AI failures, and behind many entries sits the same uncomfortable question: could the operator reconstruct what went wrong? If you cannot reproduce an AI incident, you cannot debug it, defend it to an auditor, or prove the fix actually worked.
Why you cannot reproduce an AI incident by default
A production AI run reads from live tables, feature pipelines, retrieval indexes, and reference lookups. All of those keep changing. By the time an incident lands in your queue, the upstream table has new rows, the feature job has rerun, and the vector index has been reindexed. You still have the model. You no longer have the input.
Software engineers solved this for code decades ago with version control and reproducible builds. AI teams inherited versioned models and versioned code but skipped the hardest layer: the data state at the moment of the run. Model versioning tells you which weights ran; it does not tell you which rows, which schema, and which preprocessing produced the output you are now trying to explain.
The practical test is simple. Pick any prediction your system made last Tuesday at 2:14 p.m. Can you feed the model the same bytes it saw then and watch the same answer come back? For most enterprise teams the honest answer is no, and that gap is where incidents become unsolvable.
Check the data state, not only the model
When an AI system that worked in testing fails in production, people reach for the model first. In our experience the input is often part of the cause, so check the data state alongside the model. A schema migration renamed a column and the feature now arrives as null. An upstream job started truncating decimals. A reference table went stale and the model is scoring against last quarter’s thresholds. The weights never changed; the data underneath them did.
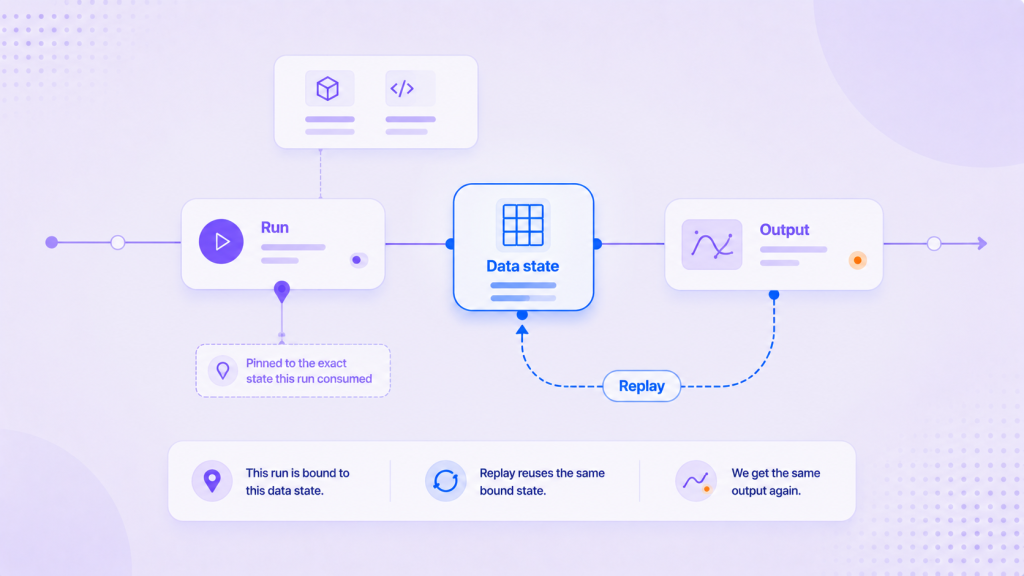
This is why reproducibility has to bind the run to a verifiable data state, not just a model tag. A saved Version captures the data a run used at the time, and a link between the run and that Version records which data it consumed. With both in place, reproduction stops being an archaeology project and becomes a replay you can trust.
A playbook to reproduce an AI incident
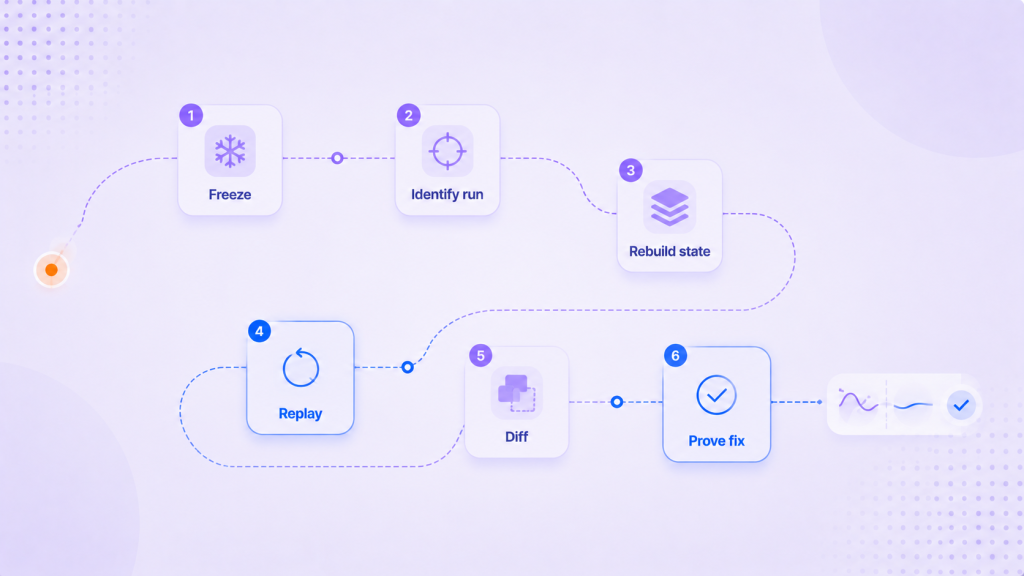
Here is the sequence we use with regulated enterprises. It assumes you have some way to pin and replay a data state; if you do not yet, the closing section covers where that fits.
1. Freeze the evidence. The moment an incident is confirmed, stop treating the involved tables and indexes as mutable. Snapshot or bind the current data state so it stops drifting while you investigate, because you cannot debug a moving target.
2. Identify the exact run. Find the specific inference or agent run that produced the wrong output: its timestamp, its request, and the record that ties it to the data used at the time. If runs are not bound to states, you are already reconstructing from logs and guesswork.
3. Recreate the input state. Recreate the data as it existed at run time, meaning the rows, the schema version, the feature values, and the retrieved context. This is the step most teams skip, and it is the step that decides whether reproduction succeeds.
4. Replay against the bound state. Run the same model version against the recreated state. If the wrong output reappears, you have reproduced the incident and isolated it to data plus model rather than to environment noise.
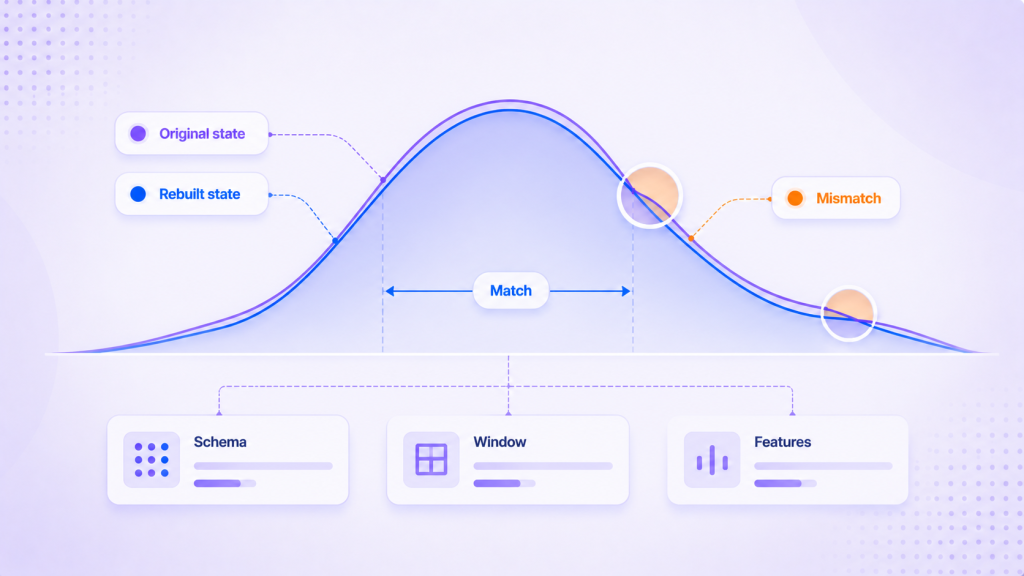
5. Compare to localize the cause. Compare the incident-time state against a known-good state. The comparison shows you which fields, rows, or schema elements changed, and that difference often points to the root cause.
6. Fix, then prove it. Apply the fix, then rerun against both the incident state and current data. Reproduction is not finished when the bug is found; it is finished when you can show the same input no longer yields the same failure.
What a reproducible incident record contains
Auditors and incident reviewers do not want a narrative. They want the artifacts. Google’s ML Test Score rubric made the same point about production readiness, scoring data and infrastructure checks with the same weight as model checks. A record that lets someone else reproduce an AI incident without your help should carry a few concrete things, and the table below separates what most teams log from what reproduction actually requires.
| Element | Commonly logged | Needed to reproduce |
|---|---|---|
| Model version | Yes | Yes |
| Code commit | Yes | Yes |
| Input data state | Rarely | Yes |
| Schema version at run time | No | Yes |
| Retrieved context or features | Partial | Yes |
| Run-to-state binding | No | Yes |
The pattern is clear. The rows everyone already fills in are the model and the code; the rows that decide reproducibility are the data state and its binding to the run. NIST makes the same point in its AI Risk Management Framework, which calls for AI systems to be documented, traceable, and auditable, not merely monitored.
Can you reproduce an AI incident today? A self-check
Run this quick diagnostic against your own stack. If you answer no to two or more, incident reproduction is currently a matter of luck.
- Can you name the exact data state a given production run consumed?
- Can you recreate that state weeks later, after upstream tables have changed?
- Can you diff the incident-time state against a known-good baseline?
- Can you rerun the model against the recreated state and get the same output?
- Can you hand all of this to an auditor without narrating it yourself?
Where this fits in CUBIG’s operating layer
Reproducing an incident is only tractable when the run was bound to a data state in the first place. For production AI, the question is not only which model ran but which data state and which execution conditions produced the result. Syntitan, CUBIG’s AI-ready data platform, prepares and checks enterprise data for a specific AI task. It diagnoses data on six axes, Usability, Integrity, Context, Consistency, Reproducibility, and Traceability, and creates a new data Version after each successful processing run, so you can see the data used at the time and compare it with the previous state.
In practice that means the data Versions this playbook depends on are saved as the work happens, not scrambled together after the fact. Tracking changes after release and linking agent runs to that data are planned for December. For the foundational concept behind this, see what AI-ready data means; for the failure modes that trigger these incidents, see why AI fails after deployment and how schema changes break production AI. For how the same reproduction discipline extends to accountable public-sector decisions, see an audit trail for AI decisions in the public sector.
Try it on your data for free. Run a sample proof and see it on your own workflow.