Operating control vs CI/CD for ML is the difference between a pipeline that ships reliably and a production result you can reproduce: CI/CD reproduces the build, while operating control binds each run to the data state that actually produced the answer.
The gap matters because even a mature pipeline stops at the build. Google Cloud’s MLOps guide grades the practice into maturity levels 0 through 2 and singles out continuous training as the one piece that only ML systems need on top of standard CI/CD. Automate all of it and you can still ship a model flawlessly yet fail to explain the number it produced last Tuesday.
What CI/CD for ML actually reproduces
Continuous integration and continuous delivery for machine learning automates the path from commit to production. It versions code, runs automated checks, packages models, and controls rollouts and rollback. When the pipeline works, the same commit yields the same deployment every time.
That discipline is real and worth keeping. CI/CD gives teams model versioning, reproducible builds, and a clean audit of what shipped and when. If your concern is “did this exact pipeline definition make it to production,” CI/CD answers it well, and I would never suggest replacing it.
The limit is narrow and specific. CI/CD pins the code and the pipeline definition; it does not pin the live data that pipeline reads once it is running. The build is frozen, but the world the build operates on keeps moving.
Why a reproducible build still gives a non-reproducible result
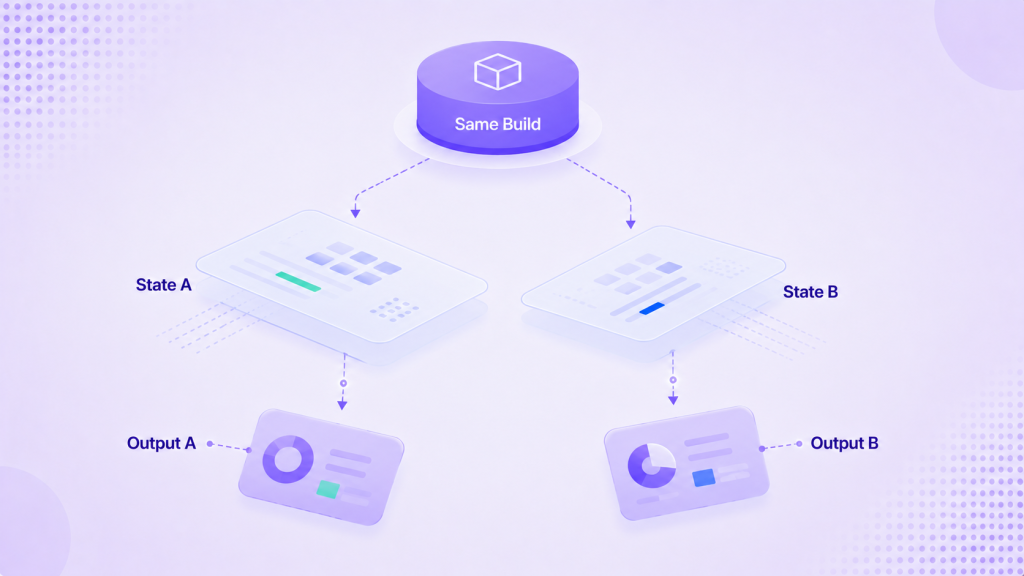
A pipeline can be byte-for-byte reproducible and still produce an answer nobody can recreate three months later. The reason sits outside the build entirely: the production data state changed after the build shipped.
Operating control vs CI/CD for ML: what each one binds
The cleanest way to see the split is to ask what each layer binds to a run. CI/CD binds code and artifacts. Operating control binds the data state and the execution conditions. You want both, because a production result depends on both.
Read the table as a division of labor, not a contest. CI/CD owns shipping. Operating control owns the run. The Partial marks are where the two overlap: CI/CD versions the pipeline that transforms data, and operating control records enough to reproduce an answer, but neither covers the other’s core job.
How the two fit together in one flow
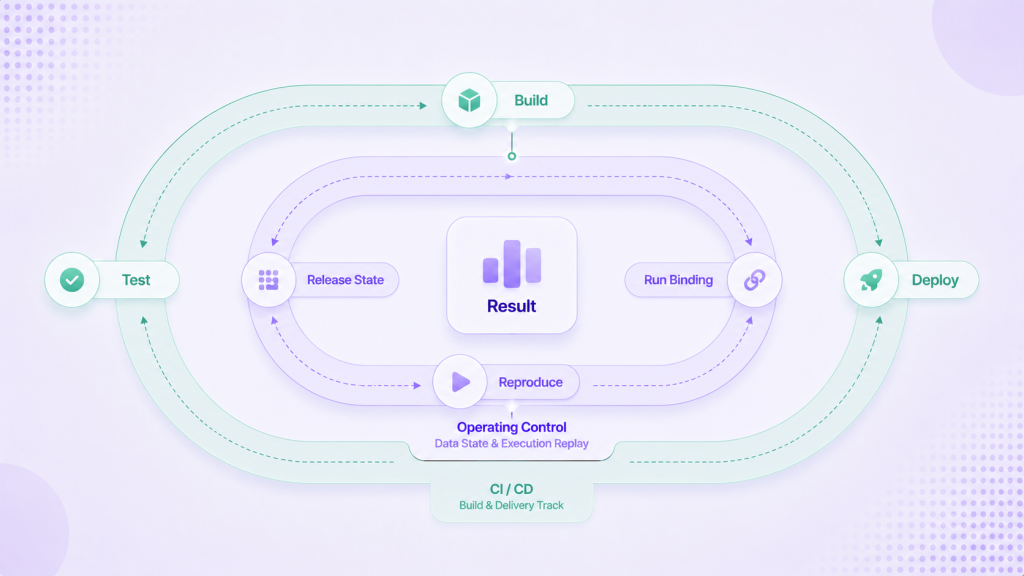
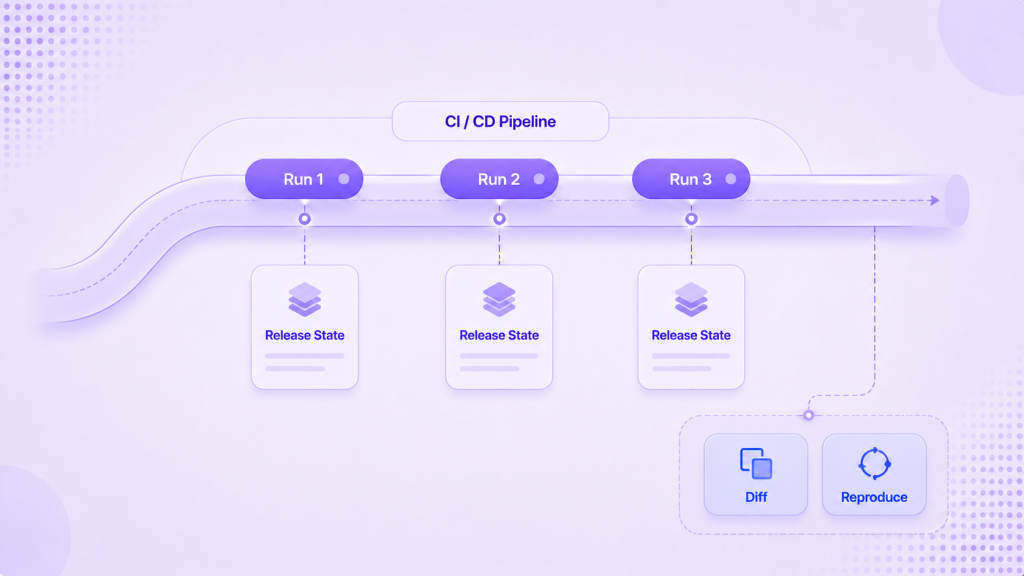
Operating control is not a replacement for your ML CI/CD; it runs inside it. Keep CI/CD for build and deploy, then add a step that links each production run to a Version: a captured, addressable record of the data used at the time and the execution conditions behind that run.
With both in place you can make two statements instead of one. CI/CD lets you say which commit produced which deployment. Operating control lets you add which data that deployment used at the time to produce a given result, and then compare that data with the previous state or with another run. Together they cover both halves of reproducibility, the code half and the data half. The code half already has a working standard: the Reproducible Builds project counts a build as trustworthy only when a deterministic process and a documented environment let an independent party rebuild the artifact and match the output. Keeping a Version of the data used at the time brings a similar bar of verification to the data half.
This is where the six readiness axes come in. Before a run is worth recording, the data behind it has to be ready for the task, so Syntitan diagnoses enterprise data on Usability, Integrity, Context, Consistency, Reproducibility, and Traceability, then applies, holds or excludes fixes and saves the result as a new Version. The axes show what to fix for a task; a high score alone does not show task fit.
A quick self-diagnostic
Run this test against your own stack. Google’s ML Test Score takes the long route, 28 tests for production readiness that weigh data and infrastructure as heavily as the model itself; the short list below covers the data-state half. If you answer “no” to more than one of these, your CI/CD is doing its job and your data state is still unbound.
- Can you name the exact data window a production run read, not just the commit it ran?
- If a source schema changed last month, would your pipeline logs show it, or would the build still read green?
- Can you compare two runs by their data state and see what moved?
- Given a result from six months ago, can you reproduce it, or only rebuild the deployment?
- When an auditor asks “why this output,” do you have the state, or only the code?
Where it fits
For production AI the question is not only which model ran; it is which data state and execution conditions produced the result. That is the layer operating control lives in, and it sits beneath your CI/CD rather than beside it. The data Version it records is the same unit that comparing data states works on, and model versioning alone leaves the same gap CI/CD does.
Syntitan, CUBIG’s AI-ready data platform, is where this work happens. It prepares and checks enterprise data for a specific AI task using the six axes above and creates a new data Version after each successful processing run, so you can see the data used at the time and compare it with the previous state. Tracking changes after release and linking agent runs to that data are planned for December. For the broader picture, see what AI-ready data means.
Try it on your data for free. Run a sample proof and see it on your own workflow.