Clean data passes type, null, duplicate, and compliance checks.
AI-ready data clears one more bar: a model can still learn from what’s left, and you can reproduce the exact data behind any result. Clean is a hygiene standard. AI-ready is an execution standard. The two get used as if they mean the same thing, and that confusion can stall a pilot that looked ready on paper.
‘Our data is clean’ is usually true. It is also a common reason the AI still fails. The checks that make data clean and the properties that make it ready are different properties, and a dataset can have the first while lacking the second. This article sets out where they diverge, why the gap stays invisible until production, and how to tell which side of the line your own data is on.
What ‘clean’ actually certifies
Cleaning earns its place. Bad data is expensive to work with, and clearing it is what cleaning addresses. So clean is a real and useful standard. When a data team says a dataset is clean, they mean it has passed a set of checks:
- Types are correct, so a date is a date and a number is a number.
- Nulls are handled, either dropped or filled, so nothing downstream breaks on a missing value.
- Duplicates are removed, so a record is counted once.
- Compliance is satisfied, so identifiers are masked or generalized to clear privacy review.
Pass all four and the data is clean. It will load, it will join, it will populate a dashboard, and it will survive an audit of its handling. None of that is in dispute. The trouble is that every one of those checks is about the form of the data, not about whether the signal a model needs survived the process.
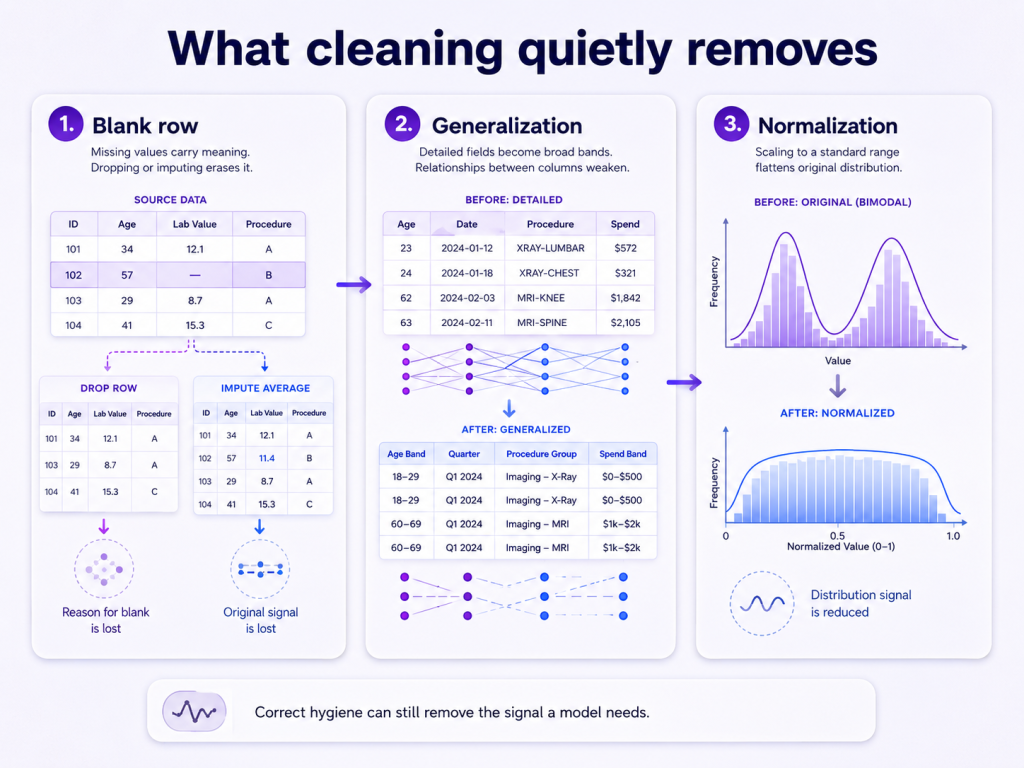
What cleaning quietly removes
Most enterprise data moves through a bronze, silver, gold pipeline. Each promotion makes the data cleaner and more consistent, and each promotion also strips out information a model was relying on. The loss happens in ordinary steps, each defensible on its own:
- A blank row is dropped or imputed. But a blank often carries meaning. A missing lab value can mean the test was never ordered, which is itself a signal. Drop the row and the model learns nothing was there; impute it to the column mean and the model learns something false. The ‘reason it was blank’ leaves with the row, and nothing records that it left.
- A field is generalized for compliance. Age becomes a ten-year band; a date becomes a quarter. Each column passes its privacy check in isolation, while the relationship between columns that the model was learning from is broken.
- A column is normalized to a clean range. It becomes comparable across sources and loses its distribution. A bimodal column that told the model two distinct populations existed flattens into a smooth ramp.
None of these is a mistake. Each is correct hygiene. The problem is that what they remove is never written down. The data clears every check and reaches the model stripped of part of what made it useful, and the subtraction stays invisible until a model trained on the residue underperforms in production.
Clean is hygiene. Ready is whether a model can learn.
This is the core distinction. Clean asks: did the data pass its checks? AI-ready asks: can a model still learn from what’s left, and can you reproduce the state it ran on? A dataset can be spotless on the first question and unfit on the second.
| Clean data | AI-ready data | |
|---|---|---|
| Standard | Hygiene | Execution |
| Asks | Did it pass its checks? | Can a model learn from it, reproducibly? |
| Optimized for | Dashboards, reporting, audit of handling | Models, LLMs, and agents in production |
| Treats a blank as | A defect to remove or fill | Possible signal to preserve and label |
| Cares about distribution? | No, tidy categories are fine | Yes, the full distribution carries the signal |
| Cares about reproducibility? | No, the latest clean version is enough | Yes, every run is tied to a fixed version you can return to |
A dashboard wants tidy categories and suppressed outliers. A model wants the full distribution, including the parts a human would dismiss as noise. So the same gold table that is ideal for a report can be the wrong input for a model, even though it is, by every check, clean.
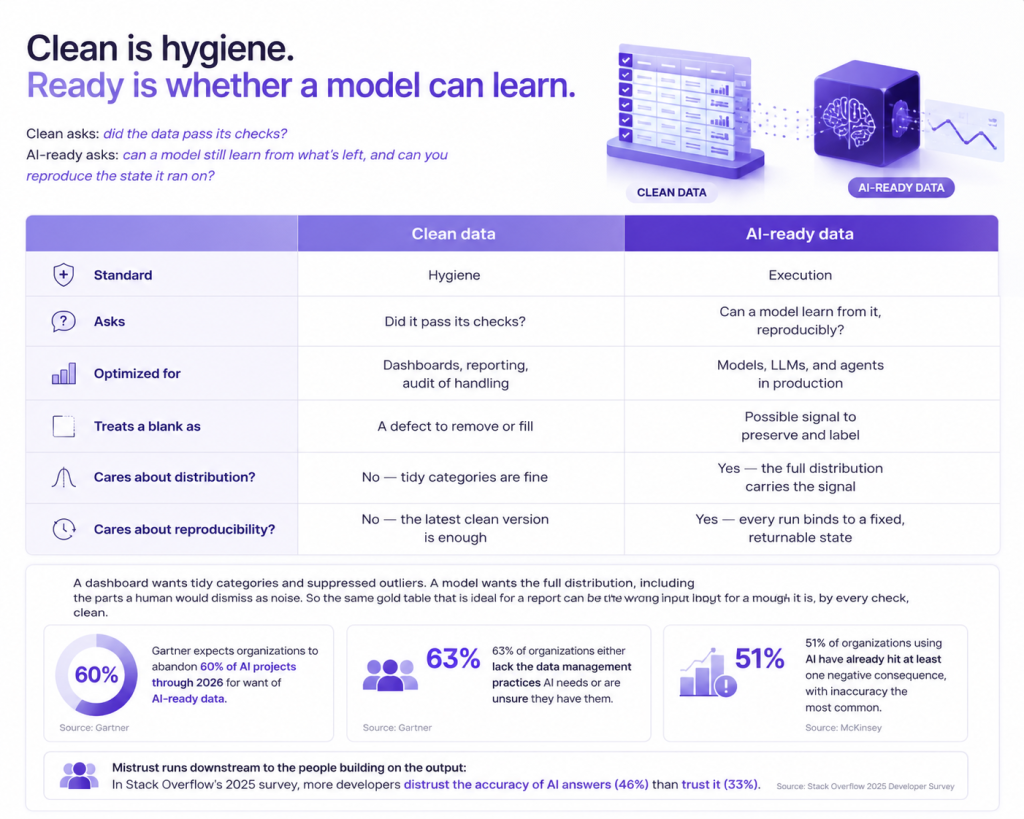
The cost of getting this wrong is not theoretical. In a survey of 1,203 data management leaders published in February 2025, Gartner found that 63% of organizations either lacked the data management practices AI needs or were unsure whether they had them, and predicted that through 2026 organizations will abandon 60% of AI projects not supported by AI-ready data. These are industry figures, not CUBIG results. When a pilot stalls, check the model and the data state together before deciding which one to fix.
The part ‘clean’ never covers: a state you can return to
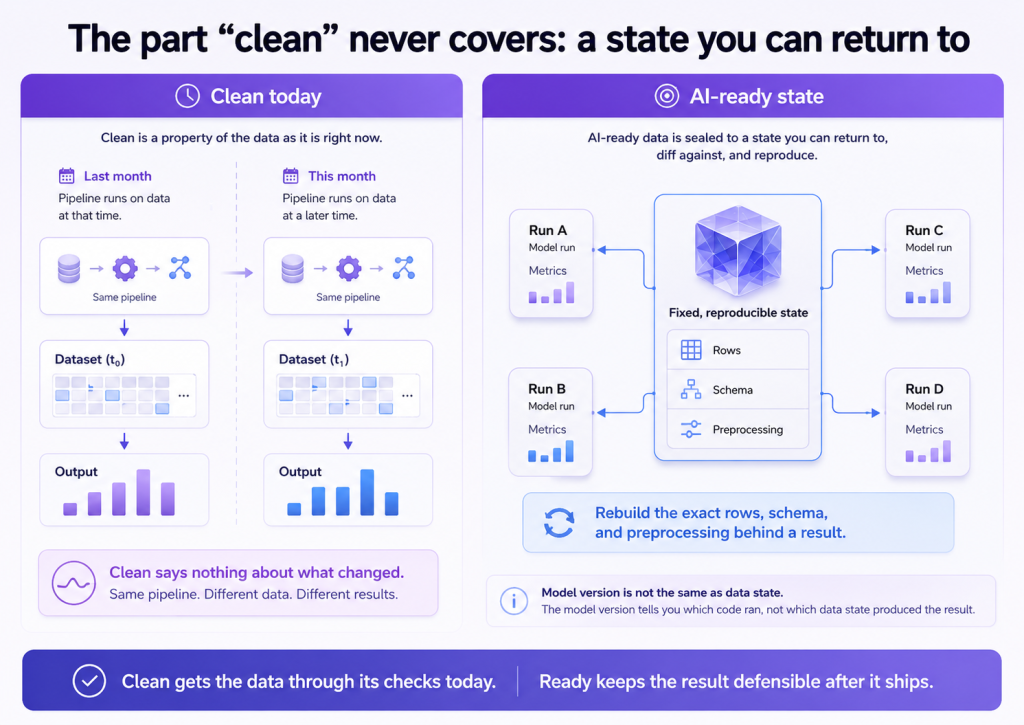
There is a second half to readiness that hygiene does not touch at all. Clean is a property of a dataset as it is right now. Production is not one moment.
The same pipeline, running on data that has shifted underneath it, produces different results next month, and ‘the data is clean’ says nothing about why.
When a model that worked last month drifts this month, the team needs to answer one question fast: what changed between the run that worked and the run that didn’t.
Cleanliness cannot answer it. Only a fixed, reproducible state can. AI-ready data, in this sense, is data sealed to a state you can return to, diff against, and reproduce, so when output is questioned you can recover the exact rows, schema, and preprocessing the result came from.
Versioning the model is not the same thing: the model version tells you which code ran, not which data state produced the result.
This is why clean is necessary but not sufficient. Clean gets the data through its checks today. Ready keeps the result defensible after it ships.
How to tell the difference on your own data
A quick check before the next planning meeting:
- In your gold tables, can you still say why a given field is blank? If not, the context is already gone, even though the table is clean.
- When a model
drifts, can you diff the data state to see what moved? If not, you are debugging blind against a moving target. - Can you take any past result and reproduce the exact data it ran on? In a regulated setting, if you cannot, you may not be allowed to use that result at all.
- Can you say which of the six axes is weak for this task, or only that the pipeline is green?
If the answers run to ‘no,’ your constraint is not model quality. It is the state of the data reaching the model, and that is a different problem with a different fix.
What to fix before deployment, and what can wait
Not every gap has to close before a model ships. Sort each one by a single question: does it change the result for the task you are about to deploy? The table below is CUBIG’s practical guide, not a fixed rule. Where the line falls depends on the task and on how much a wrong output costs.
| Gap | Fix before deployment when | Can usually wait when |
|---|---|---|
| Blanks lost their meaning | The task’s decision depends on why a value is missing, such as a test that was never ordered | The field does not feed the task’s decision or output |
| Fields were generalized for compliance | The task needs the relationship between fields, such as age and visit date together | The task uses each field on its own, such as counts in a report |
| Columns were normalized and the distribution flattened | The task depends on rare groups or tails, such as fraud or credit risk | The task works with averages and the tails do not drive the decision |
| The records, units, or goal for the task are not written down | An agent or model chooses which records, units, or targets to use on its own | A person selects the inputs for each run and checks the output |
| The run is not tied to a fixed data version | The result will be reviewed, audited, or compared after a model or data change | It is a one-off exploration no one will rerun |
The fourth row is easy to miss because the data itself looks fine. In two recent agent benchmark studies, agents sometimes chose the wrong record, unit, or goal for a task even when the data they needed was clean and available. We summarized both studies here.
Anything you leave for later still needs a note: what was deferred, why, and which task it would matter for. That note lets the next team decide quickly instead of rediscovering the gap.
How AI-ready data gets measured
Readiness is checked against a task, not certified once. Syntitan diagnoses data on six axes: Usability, Integrity, Context, Consistency, Reproducibility, and Traceability. The axes show what to fix and what to keep intact while preparing data for a specific task. The goal is not to push every score to 100, and a high score alone does not show that the data fits a particular model or agent. Clean data tends to look strong on Integrity and parts of Usability and weaker on Context, Reproducibility, and Traceability. That is the profile of data that passes review and then struggles in production. Each axis is unpacked in What Is AI-Ready Data?
Where Syntitan fits
Syntitan, CUBIG’s AI-ready data platform, prepares and validates enterprise data for a specific AI task and keeps the evidence needed when things change. Ready for Raw Data diagnoses the six axes and proposes processing steps in plain sentences that you apply, hold, or exclude. Each successful run creates a new Version, and the original Dataset stays as it was. Linking later AI and agent runs to the Version they used, and checking what to reuse after a change, is planned for December. Syntitan fills the missing layer between enterprise data management and real AI execution.
Any performance figure you see is representative until you reproduce it. Validated lift comes from your own model, on your own data, in your own environment, not from a benchmark slide.
Related: PHI Masking vs Synthetic Data · What Is DTS? · What Is Sensitive AI Workflow Enablement?