Release State vs dataset snapshot comes down to one difference: a dataset snapshot is a passive copy of data at a point in time, while a Release State is a versioned reference point, with its readiness diagnosis attached, that a team uses to show which data was behind an AI result.
Both a snapshot and a Release State claim to save the data, so teams treat them as interchangeable until a result gets challenged. That assumption gets expensive. As a Nature survey of researchers showed, reproducing results is hard even in labs built around controlled conditions. Enterprise AI teams hit a similar wall: when someone asks how a production result was produced, the conditions behind it are often hard to find again. Storing the data and being able to tie an outcome to it are two different jobs.
What a dataset snapshot actually is
A dataset snapshot captures data as it was at a moment in time. It is good for backup, rollback, and cheap storage, and most data platforms make snapshots trivial to take. Data versioning tools sit in the same family: they preserve bytes so you can retrieve an earlier copy.
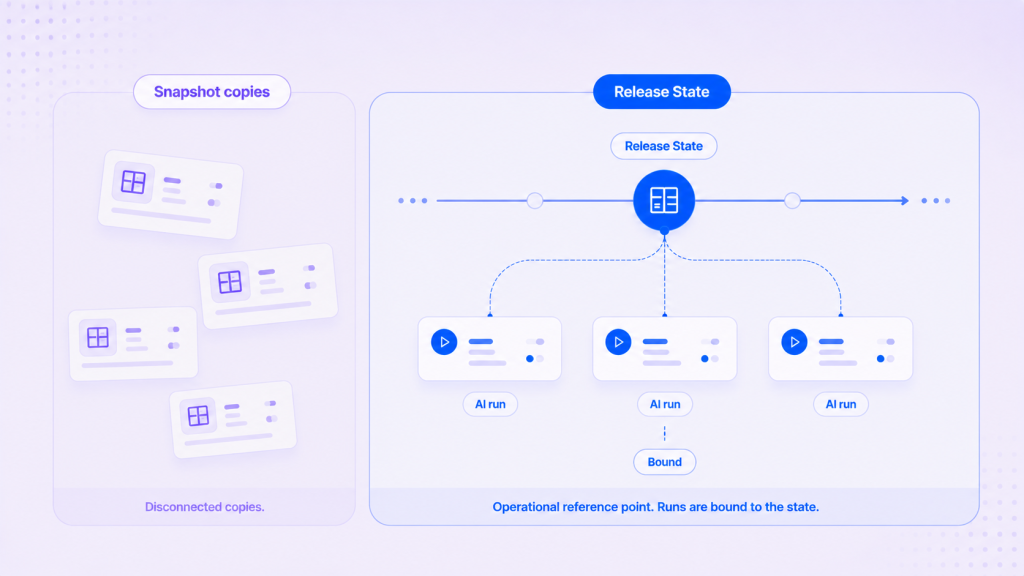
The limit is that a snapshot is passive. It sits in a bucket, disconnected from the runs that consumed it. Nothing inside a snapshot tells you which AI run used it, under what permissions, or whether the result you are now investigating came from this snapshot or another one taken the same week. When output drifts, a pile of copies leaves you guessing, because a pile of copies is not an audit trail. This is an old warning: the NeurIPS paper on hidden technical debt in machine learning argued a decade ago that data dependencies cost more than code dependencies, precisely because nothing tracks them. Having snapshots is not the same claim as being able to reproduce a result.
Teams discover this the hard way during an incident. A model output looks wrong, someone pulls the snapshots from that period, and then the questions start: which of these did the run read, was preprocessing applied before or after this copy, did the feature window include the last week of records or not? The snapshots hold the raw material, yet the one fact you need, the link from an output back to its inputs, was never captured. That missing link is why a snapshot can show what the data looked like but not what produced a given result.
What a Release State adds
A Release State is the data state used as the reference point for AI runs and review. In Syntitan this reference point is a Version: each successful processing step saves one. It differs from a snapshot in four ways, two of which are still on the roadmap, and each one matters precisely when something has gone wrong.
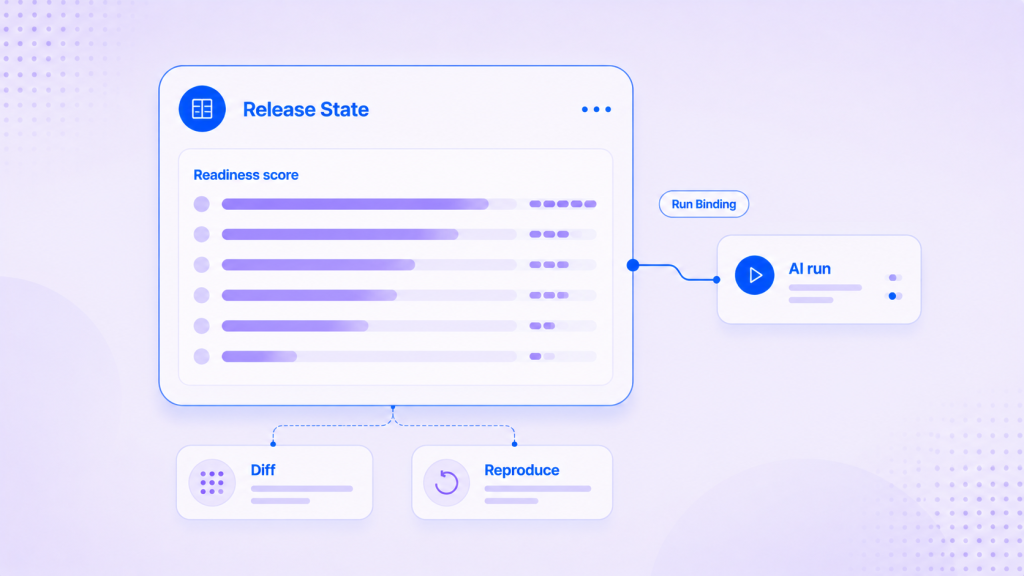
- Diagnosed. A Version carries its diagnosis on six axes, so you know what was weak in the data at the time, not merely that it existed. The axes show what to fix; a high score alone does not show that the data fits a task. A snapshot of unready data is still unready data.
- Linked. Linking each AI or agent run to the exact Version behind its output is what a snapshot lacks. In Syntitan, this run linking is planned for December.
- Comparable. Two Versions can be compared to see what changed between a working result and a broken one, whether that is schema, time window, or preprocessing.
- Reusable. Going back to a prior state for inspection, instead of hoping a snapshot still matches the run’s conditions, is planned for December along with tracking changes after release.
Release State vs dataset snapshot: side by side
| Dataset snapshot | Release State | |
|---|---|---|
| Nature | Passive copy at a point in time | Operational reference point |
| Linked to a run? | No | Planned for December |
| Diagnosed for readiness? | No | Yes, on six axes |
| Compare two states? | Manual, if at all | Built in, against the previous Version |
| Reuse a past state for a run? | Partial | Planned for December |
| Best for | Storage and backup | Production AI reproducibility |
Why the distinction shows up under pressure
The gap is invisible on a good day and decisive on a bad one. In a regulated setting the stakes get sharper: if you cannot reproduce the exact data a result ran on, you may not be permitted to rely on that result at all. The EU AI Act’s Article 12 requires high-risk AI systems to automatically record events over their lifetime so that results stay traceable, and a passive copy sitting in cold storage does not answer that on its own. A state tied to the run is designed for the question an auditor actually asks: which data produced this, and can you show it to me now?
This is also where data versioning and a plain data snapshot quietly diverge in value. Versioning proves the data existed in some form; a Release State is meant to show the run happened on a specific, diagnosed form. When a customer disputes a credit decision or a regulator reviews a model output, that second record is the one reviewers ask for. Banking supervisors put this expectation in writing back in 2011: the Federal Reserve’s SR 11-7 guidance on model risk management expects model outputs to be validated and monitored on an ongoing basis, which assumes you can show what a model actually ran on.
When to use which
Keep snapshots for what they do well, which is storage and backup. Reach for a Release State when the goal is production reproducibility, when you need to answer which data produced a result and whether you can inspect it. A snapshot can sit behind a Release State as raw material; the link to the run and the readiness diagnosis are what make the result explainable. The short version: a snapshot remembers the data, and a Release State remembers the run.
In practice the two coexist. Your storage layer keeps taking cheap snapshots on its own schedule, and that is fine. The Release State does not replace them; it sits above them, adding the diagnosis and the link to the run at the moment a run happens, so the copies you already keep become traceable rather than merely present. If you are choosing between the two, you are usually asking the wrong question. The real question is whether the runs on top of your data are tied to anything at all.
A quick check on your own setup
- For a past production result, can you name the exact data state it ran on, or only the day a snapshot was taken?
- Can you compare two points in time to see what changed, or would that be a manual reconciliation across buckets?
- If an auditor asked you to reproduce a result, would you go back to the state tied to that run, or hunt through snapshots hoping one matches?
- Do you know whether the data behind a given run was ready to run on, or only that a copy of it exists somewhere?
Where it fits in an AI-ready data layer
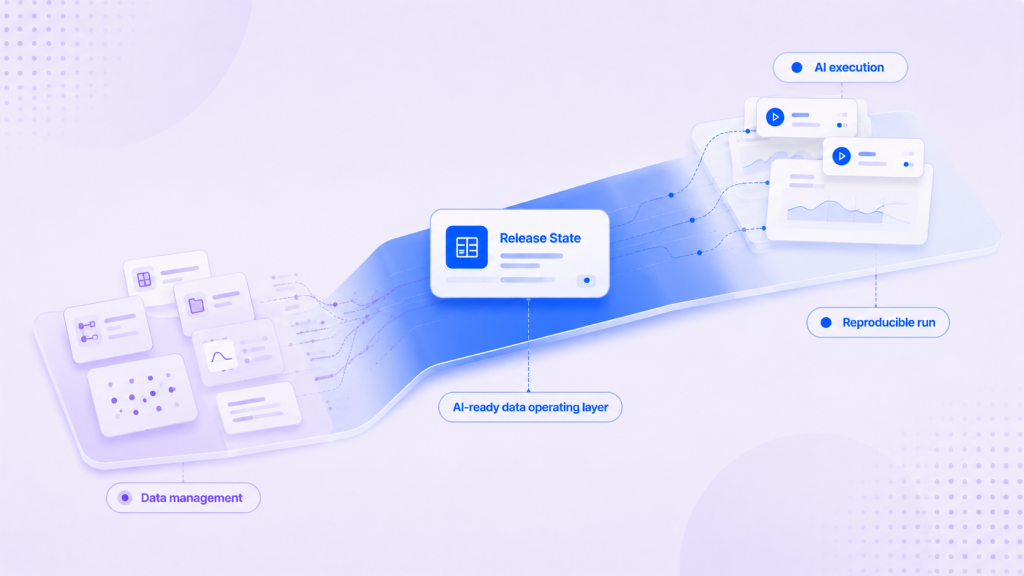
For production AI the question is not only which model ran but which data state and execution conditions produced the result. Syntitan, CUBIG’s AI-ready data platform, makes the data state operational rather than passive. It prepares and checks enterprise data for a specific AI task, then manages later changes and the evidence behind results. It diagnoses data on six axes, Usability, Integrity, Context, Consistency, Reproducibility, and Traceability, and saves each successful processing step as a Version you can compare with the previous state. Linking each AI or agent run to its Version and reusing past states are planned for December. That arc, make the data ready and keep the evidence, is the job of the operating layer for AI-ready data, the layer that sits between data management and AI execution. Any performance figure you see is representative until you check it on your own model and data.
Try it on your data for free. Run a sample proof and see it on your own workflow.
Related reading: What is Release State?, Model Versioning Is Not Enough, and How Diff Works on Data State.